Torna alle skill
co-researcher
di poemswe
Codex—Non ancora valutato
La tua valutazione
Sintesi
A professional research suite for conducting rigorous academic research using specialized agents and multi-platform CLI commands. Compatible with Claude Code, Gemini CLI, OpenAI Codex, and OpenCode.
Descrizione
# Co-Researcher (v2.1.0)
A professional research suite for conducting rigorous academic research using specialized agents and multi-platform CLI commands. Compatible with **Claude Code**, **Gemini CLI**, **OpenAI Codex**, and **OpenCode**.
## Installation
### Claude Code
**Option 1: Slash commands**
```
/plugin marketplace add poemswe/co-researcher
/plugin install co-researcher
```
**Option 2: Claude CLI**
```bash
claude plugin install poemswe/co-researcher
claude plugin install co-researcher
```
### Gemini CLI
**Option 1: From GitHub**
```bash
gemini extension install https://github.com/poemswe/co-researcher
```
**Option 2: From Local Directory**
```bash
cd /path/to/co-researcher
gemini extension link .
```
### Codex
**Option 1: Ask Codex (Agentic)**
Tell Codex:
```text
Fetch and follow instructions from https://raw.githubusercontent.com/poemswe/co-researcher/main/.codex/INSTALL.md
```
**Option 2: Manual Setup**
```bash
# 1. Clone this repo to ~/.codex/skills/co-researcher
# 2. Add hook to ~/.codex/AGENTS.md
# 3. Run:
~/.codex/skills/co-researcher/.codex/co-researcher-codex bootstrap
```
See [.codex/INSTALL.md](.codex/INSTALL.md) for details.
### OpenCode
**Option 1: Ask OpenCode (Agentic)**
Tell OpenCode:
```text
Fetch and follow instructions from https://raw.githubusercontent.com/poemswe/co-researcher/main/.opencode/INSTALL.md
```
**Option 2: Manual Setup**
```bash
# 1. Clone this repo
# 2. Run the installer:
./.opencode/install.sh
```
See [.opencode/INSTALL.md](.opencode/INSTALL.md) for details.
## Native Platform Parity
The suite provides native research commands across all supported platforms:
| Feature | Command (Claude) | Slash (Gemini) | Skill (Codex) |
|---------|------------------|----------------|---------------|
| **Research Project** | `/research` | `/research` | `$research` |
| **Methodology** | `/methodology` | `/methodology` | `$methodology` |
| **Critical Analysis** | `/analyze` | `/analyze` | `$analyze` |
| **Bibliography** | `/bibliography` | `/bibliography` | `$bibliography` |
| **Synthesize** | `/synthesize` | `/synthesize` | `$synthesize` |
| **Peer Review** | `/review` | `/review` | `$review` |
| **Ethical Risk** | `/ethics` | `/ethics` | `$ethics` |
| **Grant Proposal** | `/grant` | `/grant` | `$grant` |
## Research Orchestration Engine
The `/research` command features intelligent agent orchestration that automatically:
- Analyzes your research question
- Selects optimal agents for your specific needs
- Creates an execution plan with clear phases
- Coordinates multi-agent workflows
### Usage Modes
**Interactive Mode** (default - recommended):
```bash
/research "impact of social media on teenage mental health"
```
Review and approve the execution plan before agents run.
**Auto Mode** (for trusted workflows):
```bash
/research "climate change mitigation strategies" --auto
```
Executes the plan automatically without confirmation.
**Plan-Only Mode** (for review):
```bash
/research "AI ethics frameworks" --plan-only
```
Generates execution plan but doesn't run it.
### Example Workflow
```bash
# 1. Start research with orchestration
/research "effectiveness of remote work on productivity"
# The engine will:
# - literature-reviewer: Find recent studies on remote work outcomes
# - critical-analyzer: Evaluate methodology and bias in key studies
# - quant-analyst: Interpret effect sizes and statistical significance
# - hypothesis-explorer: Map variables (work location, productivity metrics, confounds)
# 2. Review generated plan and approve execution
# 3. Agents run in coordinated sequence
# 4. Receive integrated findings
```
### Templates
Pre-configured agent combinations for common scenarios:
```bash
/research "topic" --template=quick # Fast literature scan
/research "topic" --template=rigorous # Full systematic review
/research "topic" --template=comprehensive # Deep multi-method analysis
```
## Specialized Skills
The suite includes PhD-level research skills, each governed by **Systemic Honesty** principles.
- **critical-analysis**: Riguous logic checking and fallacy detection
- **ethics-review**: IRB compliance and privacy risk assessment
- **grant-writing**: Funding strategy and proposal development
- **hypothesis-testing**: Variable mapping and experimental design
- **academic-writing**: Eliminating AI-isms from research prose
- **lateral-thinking**: Cross-domain analogies and first-principles reasoning
- **literature-review**: Systematic search and citation analysis
- **multi-source-investigation**: Cross-validation across diverse sources
- **peer-review**: Manuscript critique and methodological review
- **qualitative-research**: Thematic analysis and coding
- **quantitative-analysis**: Statistical power and effect size interpretation
- **research-manager**: Dynamic task scaffolding and polyglot session persistence
- **research-methodology**: Design selection and validation
- **research-synthesis**: Narrative synthesis with uncertainty quantification
- **systematic-review**: PRISMA-standard systematic review guidance
- **using-co-researcher**: Orients Claude to all available skills in the suite; run once per session to activate the full protocol set
## Evaluation Framework
Verify agent performance with the v2.0 benchmark system:
```bash
cd evals
python run_eval.py all -j 4 --model "codex:gpt-5.2 high"
```
### Features
- **Parallel Runner**: Multi-threaded execution with `-j` (jobs) flag
- **Dynamic Rubrics**: 6 specialized rubrics matched to agent skills
- **Extended Targeting**: Support for specific versions and reasoning levels
- **Persistent Indexing**: Rebuildable `latest/index.md` summary
### Benchmark v2.0
Two-file architecture for scalability and transparency:
**Dashboard Data** (`benchmark_overview.json` ~900B):
- Lightweight run metadata and summary stats
- Fast dashboard load times (10-50x improvement)
**Test Details** (`test_results_detail/{run_id}.json` ~500KB):
- Full agent outputs and judge evaluations
- Rubric-by-rubric scoring breakdowns
- Must-include analysis and justifications
**Arena Dashboard**:
View live interactive dashboard at **[coresearcher.poemswe.com](https://coresearcher.poemswe.com)**
Or run locally:
```bash
open evals/index.html
```
Features: Model leaderboards, capability matrices, score trends, and detailed test breakdowns with performance ratings (Excellent/Good/Fair/Poor).
## Architecture
- `skills/`: Specialized research skills (Markdown).
- `commands/`: Unified platform commands (.md for Claude, .toml for Gemini).
- `.codex/skills/`: Native repository skills for Codex.
- `evals/`: 22 test cases and Python runner.
- manifests: `gemini-extension.json`, `AGENTS.md`, `GEMINI.md`.
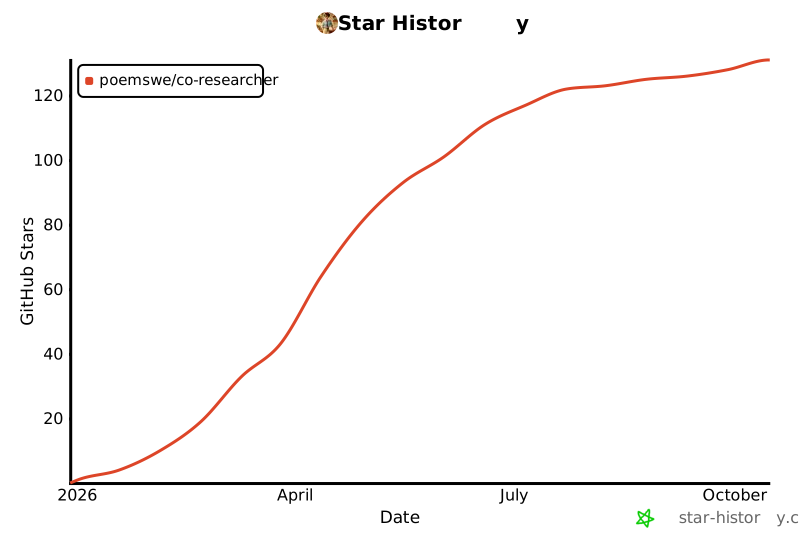
## Star History
[](https://star-history.com/#poemswe/co-researcher&Date)
## License
MIT
Installazione
Installa la skill da https://github.com/poemswe/co-researcherQuesta skill non è pubblicata sul registro ClawHub. Incolla il prompt nel tuo agente di coding — Claude Code, Cursor, Codex — e installerà la skill direttamente dal repository sorgente.
Apri il repository